Every document,
trusted by AI.
Luminir Document Parser is an on-premise document parser built by LEMONG. It turns HWP, PDF, Office files, images and more into HTML and JSON that keep headings, tables and reading order. Installed on-premise, your data never leaves your organization.
Luminir Document Parser supports HWP/HWPX, PDF, Word, PowerPoint, Excel, images and more.
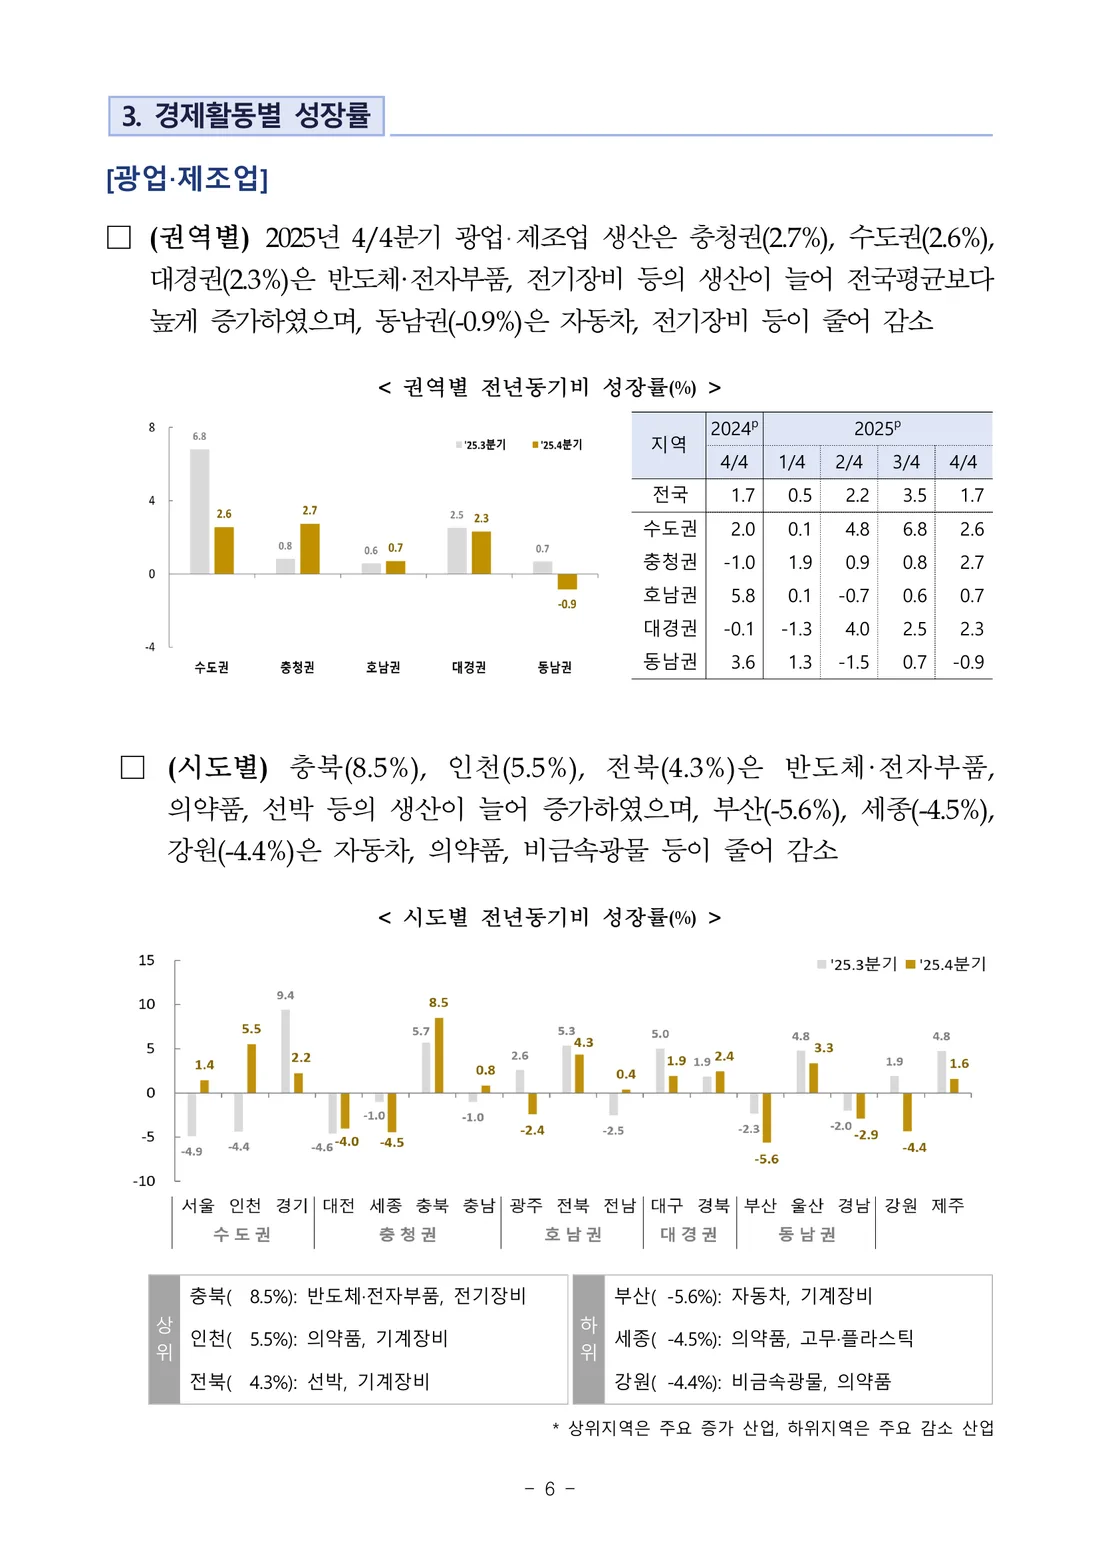
3. 경제활동별 성장률
[광업·제조업]
□ (권역별) 2025년 4/4분기 광업·제조업 생산은 충청권(2.7%), 수도권(2.6%), 대경권(2.3%)은 반도체·전자부품, 전기장비 등의 생산이 늘어 전국평균보다 높게 증가하였으며, 동남권(-0.9%)은 자동차, 전기장비 등이 줄어 감소
< 권역별 전년동기비 성장률(%)>
| 25.3분기 | 25.4분기 | |
| 수도권 | 6.8 | 2.6 |
| 충청권 | 0.8 | 2.7 |
| 호남권 | 0.6 | 0.7 |
| 대경권 | 2.5 | 2.3 |
| 동남권 | 0.7 | -0.9 |
| 지역 | 2024 | 2025 | |||
| 4/4 | 1/4 | 2/4 | 3/4 | 4/4 | |
| 전국 | 1.7 | 0.5 | 2.2 | 3.5 | 1.7 |
| 수도권 | 2.0 | 0.1 | 4.8 | 6.8 | 2.6 |
| 충청권 | -1.0 | 1.9 | 0.9 | 0.8 | 2.7 |
| 호남권 | 5.8 | 0.1 | -0.7 | 0.6 | 0.7 |
| 대경권 | -0.1 | -1.3 | 4.0 | 2.5 | 2.3 |
| 동남권 | 3.6 | 1.3 | -1.5 | 0.7 | -0.9 |
How we differ from other products
Plain text extractors pull out only the characters and throw away tables and column layouts.
Data built this way leads to missed searches and wrong AI answers.
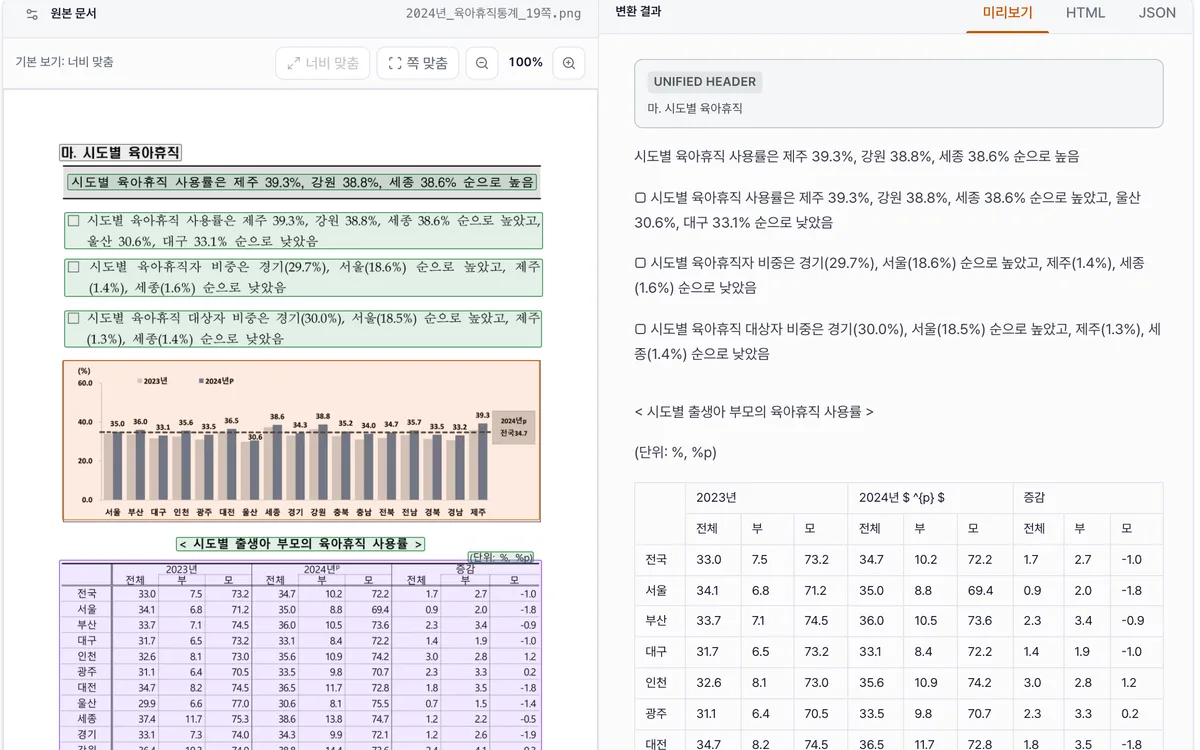
Check results side by side with the original
Anyone, not only developers, can check on screen whether a conversion is right.
Your data stays protected
Works even on closed networks with no internet connection.
- On-premise and closed networksInstalled as containers on a Linux server with an NVIDIA GPU.
- Runs without external AI servicesLayout analysis and recognition models are installed together on your servers, so documents never leave your organization and your data stays protected.
- Access control and audit logsAdmin and user roles are separated, and original documents are stored encrypted. A record is kept of who handled which document and when.
- Business systemsREST API
- Luminir Document ParserRecognition models included, GPU server
- Result storageKeeps HTML and JSON
- RAG search systemReceives HTML and JSON
Four steps to convert a document
Accept documents
Takes 12 file types as they are, including HWP, PDF, Word, PowerPoint, Excel and images, with no conversion first.
Layout analysis
Finds where titles, body text, tables, figures and headers are on each page and decides the reading order.
Recognition by region
Reads body text as text and tables as rows and columns, merged cells included. Formulas in PDFs and scans come out as LaTeX, and charts and flowcharts are organized into tables.
Export
Results come as HTML and JSON. The JSON holds the type, page number and coordinates of every element (sheet and cell range for Excel). Headers and page numbers are labeled, so you can filter them out when you do not need them.
Accuracy on public benchmarks
The closer a score is to 1.0, the closer the result is to the answer.
- 0.914Overall score combining reading order, tables and headingsHigher than the public #1 score (0.907)
Higher than the public #1 in all three areas: reading order, tables and headings.
opendataloader-bench ranking (highest first) Rank Engine Score 1 Luminir Document Parser 0.914 2 opendataloader (hybrid) 0.907 3 Commercial parser A 0.885 4 docling 0.882 5 marker 0.861 6 unstructured (hi_res) 0.841 The top 5 on the opendataloader-bench public leaderboard, shown with the Luminir score measured with the same scoring code (self-measured). - 0.759Overall score combining text, tables, reading order, headings and positionsHighest score among installable engines
Measured on real Korean documents such as the Official Gazette, statistical tables and reports. The element position score is 0.976.
KoOCR-Bench ranking (highest first) Rank Engine Score 1 Commercial parser B (cloud API) 0.773 2 Luminir Document Parser 0.759 3 Commercial parser C 0.755 4 mineru-4 (advanced) 0.752 5 paddleocr-vl-1.6 0.748 6 unlimited-ocr 0.745 The top 5 in the KoOCR-Bench published results (2026-10-05), shown with the Luminir score measured with the same scoring code (self-measured). - 0.962How closely table structure and content match the answer (TEDS)Higher than the public leaderboard #1 score (0.961)
Compared with the commercial parser results published with the benchmark, using the same scoring code. Table detection (F1) is 0.973.
DP-Bench ranking (highest first) Rank Engine Score 1 Luminir Document Parser 0.962 2 Commercial parser D 0.961 3 Commercial parser D (enhanced mode) 0.956 4 Commercial parser E 0.955 5 Commercial parser F 0.907 The top 4 on the DP-Bench public leaderboard (2026-02-09), shown with the Luminir score measured with the same scoring code (self-measured).
What it is used for
Q&A on regulations and guidelines
Turns rulebooks, work guidelines and manuals into data for RAG search, keeping their clauses and table structure.
Clearing out piles of HWP files
Converts years of accumulated HWP documents in one go, without turning them into PDF first. If a job is interrupted, there is no need to start over.
Statistical tables and reports as data
Extracts statistical tables full of merged cells as HTML tables with rows and columns, so they move easily into Excel or a database.
Pointing to the source
Every element has source coordinates, so the paragraph behind an AI answer can be highlighted right on the original.
Input and output formats
Input INPUT
- HangulHWP, HWPX
- PDFPDF
- WordDOC, DOCX
- PowerPointPPT, PPTX
- ExcelXLS, XLSX
- ImagesPNG, JPG, JPEG
Output OUTPUT
- HTMLA document that separates headings, tables and figures and opens right in a browser
- JSONStructured data with the type and position of every element
- APIREST API integration from upload to result retrieval
Installs as containers on a Linux GPU server
- Deployment
- On-premise (installed on your servers), cloud
- Installation
- Containers (Docker)
- Operating system
- Linux
- GPU
- NVIDIA GPU
GPU memory, CPU, memory and storage are recommended based on your document volume and number of concurrent users.
21 frequently asked questions
Can’t find your answer? Ask us through Contact us.
About the product
Luminir Document Parser is a document parser built by LEMONG that supports both on-premise and cloud deployment. It finds titles, body text, tables and figures in HWP, HWPX, PDF, Word, PowerPoint, Excel and scanned image documents, and converts them into HTML and JSON in reading order. It is used to build data for RAG (AI that searches documents to answer) systems.
It is used for Q&A on regulations and guidelines, batch conversion of accumulated HWP documents, turning statistical tables and reports into data, and showing where an AI answer came from in the original. You can feed rulebooks and manuals into a search system with their clauses and tables intact, or move statistical tables full of merged cells into Excel or a database with their rows and columns as they are.
You can check its performance in numbers. Luminir Document Parser publishes its scores on 4 public benchmarks, including the Korean public-document benchmark KoOCR-Bench, together with the measurement conditions, and we will show you the results on your own documents.
Documents and results
It accepts 12 file types: HWP and HWPX, PDFs with text and scanned PDFs, Word (DOC, DOCX), presentations (PPT, PPTX), Excel (XLS, XLSX) and images (PNG, JPG, JPEG), as they are, with no separate conversion for each format.
Yes, just put in HWP and HWPX files as they are. It reads the paragraphs and tables of Hangul files directly. Batch conversion of many files at once is supported, and if it stops partway, it resumes from where it stopped.
Yes. For scanned PDFs and photos, it finds table regions in the page image and reads them as rows and columns. On KoOCR-Bench, made of 604 pages of real Korean documents such as the Official Gazette and statistical tables, we measured an overall score of 0.759 (self-measured). We will show you the results on your own documents.
Yes. Tables with merged cells are exported as HTML tables that carry the row and column merge information. On the public benchmark DP-Bench, we measured a table structure and content score (TEDS) of 0.962 (self-measured).
In HTML and JSON. The HTML is a document that separates headings, tables and figures and opens right in a browser, and the JSON holds the type, page number, reading order and coordinates of each element (sheet and cell range for Excel). A REST API covers everything from upload to retrieving results.
They are kept and labeled by type. Headers, footers and page numbers are marked separately, so they are easy to filter out if you want them out of your search data.
Formula regions in PDFs and scanned documents are read as LaTeX (a notation for formulas).
Yes. Every element has a page number and coordinates, so the region can be highlighted on the original document (sheet and cell range for Excel). The element position score on KoOCR-Bench is 0.976 (self-measured).
Accuracy
They are self-measured by LEMONG using the data and scoring code each benchmark has published, as they are. The measurement conditions are published on the benchmark details page.
On the Korean public-document benchmark KoOCR-Bench (604 pages, including the Official Gazette, statistical tables and reports), we measured an overall score of 0.759 (self-measured). It is the highest score among the installable engines on the public leaderboard.
Yes. It first finds the regions on the whole page, decides the reading order, and then reads each region. On opendataloader-bench, made of 200 English pages, we measured a reading order score of 0.944 (self-measured).
Deployment and security
Both are supported. On-premise, it is installed on your servers and works even on closed networks with no internet connection. In the cloud, documents are processed on LEMONG servers, so you do not need to prepare a server. We will advise you based on your security policy and document volume.
A Linux server with an NVIDIA GPU and a container (Docker) runtime. The recognition models are installed on your server too, so it runs inside your internal network without external AI services. We will recommend detailed server specs based on your document volume and number of concurrent users.
On-premise, the layout analysis and recognition models are installed together on your servers, so documents are processed inside them. It runs inside your internal network without external AI services. In the cloud, documents are processed on LEMONG servers.
Yes. It separates admin and user roles, stores original documents encrypted, and keeps audit logs of document uploads, views, downloads and deletions.
Through a REST API. File upload, conversion progress and result retrieval are all available through the API, so it can plug into your search or RAG system.
Yes. Batch conversion of many files at once is supported, and if it stops, it resumes from where it stopped. We will measure processing time on your own documents.
Getting started
Consultation, then a test on your documents, then contract, installation and integration. In the consultation we check your document types and volume and your server environment, and then explain the timeline and terms.
Talk to us about Luminir
Tell us which documents and work you want to bring AI to.
We will suggest a setup that fits your environment.
- support@lemong.ai
- Phone
- 02-6958-6868
Tell us your organization, document types and volume, and server setup, and we will get back to you quickly. We reply in English or Korean.